Table of Content
When Every DLP Alert Is a False Alarm: Making Data Protection Accurate Enough to Enforce
-
November 16, 2026
-
A scenario: the alarm nobody hears
Here is a typical scenario.
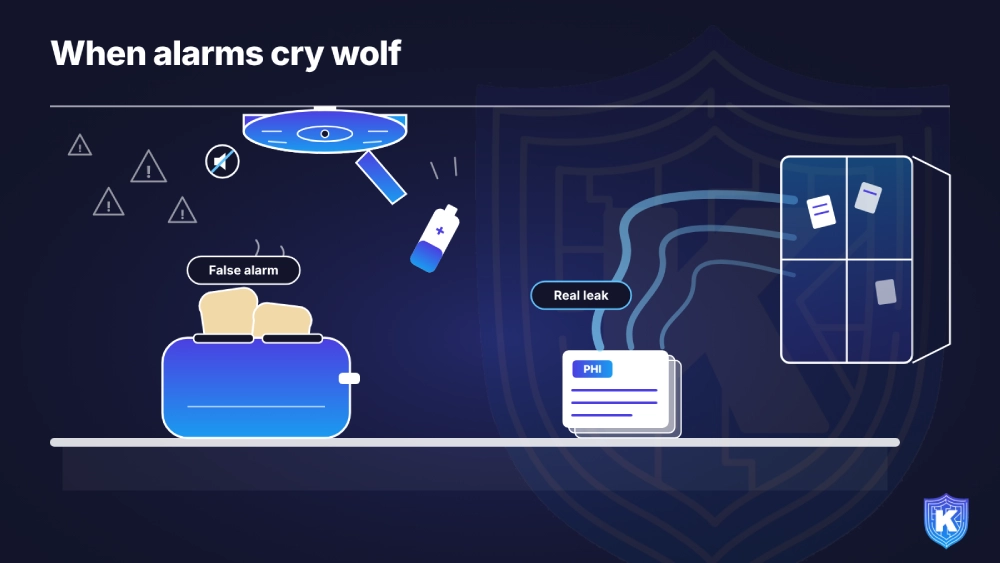
A 900-person healthcare billing company rolls out DLP ahead of its SOC 2 audit. The out-of-the-box rule for Social Security numbers fires on claim IDs, ZIP+4 codes and test data. Within a month, the two-person security team faces hundreds of alerts a week, nearly all harmless. Finance complains that uploads get blocked during month-end close.
So the team does what many teams do. It switches the noisiest rules to monitor-only and stops reading the queue.
Months later, a billing analyst pastes a spreadsheet of patient balances into a personal AI chatbot to “clean up the formatting,” then saves a copy to personal cloud storage. Both events are logged. Neither is seen until a quarterly review, long after the data has left.
The tool worked as configured. It just couldn’t tell a real leak from a false alarm, so nobody trusted it enough to let it act.
The problem: DLP that detects after the fact
- 73% had at least one confirmed data loss incident in the past 24 months.
- Of those, only 16% said DLP blocked their most significant incident before the data left.
- 54% triage DLP alert queues where most alerts turn out to be false positives.
- 90% saw at least one measurable impact from alert fatigue in the past year, and 21% reported staff departures they attribute to DLP alert burden.
- 71% faced business pushback on enforcement, and 54% of all respondents softened enforcement in some form.
How Gen AI changed it
- Data stopped moving as files. It now moves as pasted text, prompts, summaries and screenshots. In the same CSA survey, Gen AI was the most-cited exfiltration risk (48%), yet only 22% strictly block it and only 29% can produce a routine 30-day report of sensitive data sent to Gen AI tools.
- Paraphrase beats patterns. Ask an AI tool to rewrite a customer list as prose and the result no longer matches a nine-digit pattern or a keyword list. The data is the same; the shape isn't.
- Volume went up. More copy-and-paste, more tools and more uploads mean more events running through the same brittle rules, and more alerts.
- Agents act on users' behalf. Gartner notes that many agentic AI workflows originate on the user's device, so DLP now has to cover "both user and agentic workflows" (Gartner Market Overview for DLP, Sept 2026).
Why legacy approaches fall short
- Regex and keyword rules match shapes, not meaning. A nine-digit number might be a Social Security number or an invoice. They miss paraphrased text, images and most source code, and they flag everything that merely looks similar.
- Fingerprinting and exact-match setups are accurate for known records but take real effort to build and maintain. They miss new or reshaped data.
- Network-only and cloud-proxy inspection misses laptops off the corporate network, desktop and end-to-end encrypted apps, and the clipboard. It also lacks the device and user context needed to judge intent.
- Block-everything policies create pushback, then exceptions. In the CSA survey, 66% of teams that faced pushback reduced enforcement for specific teams or use cases.
- Heavy suites assume a dedicated team to tune policies every week. Most companies with 100 to 2,500 employees don't have one.
What a modern approach looks like
- 1. Classify by meaning. Recognize a patient record or a pricing sheet by what it is, even after it's been reworded, converted or screenshotted.
- 2. Add context to content. Who is moving it, from which app and device, to where. The same file going to a sanctioned CRM and to a personal chatbot are different events.
- 3. Respond in proportion. Allow, warn with a short justification, or block. Coaching in the moment cuts both leaks and pushback.
- 4. Measure accuracy like a product metric. Track the false-positive rate and time to triage, and review them monthly.
- 5. Start narrow, then widen. Enforce first on the few data types that would hurt most, then expand as confidence grows.
- 6. Respect privacy. Keep sensitive content on the device where possible, so the control doesn't become a new copy of the data.
How Kitecyber helps
- Classification that understands content. A hybrid approach pairs LLM-based understanding with on-device pre-processing, so sensitive content stays on the endpoint. Kitecyber reports 90%+ classification accuracy across 80+ data categories, including PII, PHI, payment data, IP and source code, and positions it as more accurate than pattern matching.
- Six context signals per decision. Device posture, OS activity, process activity, data classification, user activity and network activity all feed each allow, warn or block decision.
- Coverage where data actually moves. Browsers and installed apps, real-time copy and paste, Gen AI paste and upload, SaaS and cloud uploads, USB and network drives, end-to-end encrypted apps, and Teams, Zoom and Slack. Policies keep working offline.
- Context that survives reshaping. Data lineage follows content through screenshots, encoding and file conversion, and UEBA adds behavioral anomaly detection.
- Built for lean teams. One agent at under 2% CPU, about a day to deploy, pre-built policies for frameworks such as GDPR, SOC 2, HIPAA, PCI DSS and ISO 27001, and self-hosted, bring-your-own-keys or SaaS deployment. When AI agent activity and sensitive data combine suspiciously, an incident report is generated in minutes.
SME decision-maker checklist
- 1. In a deployment like ours, what share of alerts turn out to be false positives, and how do you measure it?
- 2. How does your classifier handle paraphrased, summarized, reformatted or screenshotted data?
- 3. What context besides content goes into each decision: user, device, app, destination?
- 4. Can we warn and coach, not only block, and capture a short justification?
- 5. Does sensitive content leave the device to be classified? If so, where is it processed and stored?
- 6. Does enforcement work off-network and in desktop, collaboration and Gen AI apps?
- 7. Quick win this week: sample 50 DLP alerts from last month and count how many were real. That number is your baseline.
Compliance angle
- ISO 27001:2022: Annex A 8.12, Data leakage prevention, calls for measures applied to systems, networks and other devices that process sensitive information.
- HIPAA Security Rule: audit controls and transmission security (45 CFR 164.312) assume someone reviews activity and that ePHI is protected in transit.
- PCI DSS 4.0: Requirement 12.10.7 expects incident response procedures when stored card numbers are found where they shouldn't be. Accurate detection is what triggers them.
- SOC 2: the Confidentiality criteria and system monitoring (CC7) look for controls that detect and act on anomalies.
- GDPR: Article 32 requires appropriate security, and Article 33's 72-hour breach notice depends on knowing quickly what left.
- CMMC and NIST SP 800-171: requirement 3.1.3 calls for controlling the flow of CUI.
Key takeaways
- Noise, not deployment, is what breaks most DLP programs: false alarms lead teams to soften enforcement.
- Accuracy comes from meaning plus context, judged on the device at the moment data moves, including into Gen AI tools.
- Start with warn-and-coach on a few critical data types, measure precision, then block with confidence.
Ajay Gulati
Ajay Gulati is a passionate entrepreneur focused on bringing innovative products to market that solve real-world problems with high impact. He is highly skilled in building and leading effective software development teams, driving success through strong leadership and technical expertise. With deep knowledge across multiple domains, including virtualization, networking, storage, cloud environments, and on-premises systems, he excels in product development and troubleshooting. His experience spans global development environments, working across multiple geographies. As the co-founder of Kitecyber, he is dedicated to advancing AI-driven security solutions.